XPerf:让模型路由从“选最强模型”走向“预测谁最适合当前问题”From Predicting Model Performance to Better Model Routing
研究时间:2026 年 9 月起
状态:持续迭代中
当一个产品可以同时调用多个大语言模型时,“哪个模型最强”其实不是最有用的问题。不同模型在代码、数学、知识问答、长文本理解和 Agent 任务上的优势并不完全相同,而调用成本、延迟和输出长度也各有差异。
因此,更实际的问题是:
面对当前这个具体请求,哪个模型最适合回答它?
XPerf 是 Telluvian 路由系统中的模型表现预测组件。它接收用户的 prompt,并为每个候选模型预测预期表现,例如:
| 候选模型 | 预期表现 |
|---|---|
| Model A | 80% |
| Model B | 60% |
| Model C | 47% |
XPerf 并不直接负责整个调用决策。成本、延迟、缓存、输出长度和产品策略仍由外层系统处理;它首先试图把一个更基础的问题做好:同一个 prompt 对不同模型而言,成功的可能性分别有多大?
整个项目也是围绕这个问题逐渐展开的。最初,我们先建立最简单的 router baseline;随后加入 embedding 和语言模型内部 activation;再逐步审计、扩展数据并改进评测方式。随着实验推进,研究问题也从“能否预测模型表现”逐渐变成了更困难的一件事:预测得准之后,为什么仍然不一定选得对?
一个 Router 怎样才算真的有用?
本文中 router 的准确率,指在测试 prompt 中,router 所选模型给出正确答案的比例。模型路由很容易被一个看起来不错的准确率误导。假如一个 router 能达到 85% 的准确率,但始终调用同一个最强模型就能达到 87%,那么这个 router 虽然“会预测”,却没有创造真正的选模价值。
因此,项目最开始并没有急着训练复杂模型,而是先建立一套之后一直沿用的评测框架。其中两项检验泛化能力:在“未见过的 prompt”测试中,同一个 prompt 不会同时出现在训练集和测试集里;在“未见过的 benchmark”测试中,整个 benchmark 都不参与训练。
| 评测方式 | 它回答的问题 |
|---|---|
| Best single model | 如果永远固定选择一个模型,最好能做到什么程度? |
| Oracle | 如果事后知道所有模型的真实表现,理论上还能提升多少? |
| 未见过的 prompt | 面对同一类任务中的新问题,是否还能泛化? |
| 未见过的 benchmark | 面对训练时完全没见过的任务类型,是否还能迁移? |
| Per-benchmark / headroom | 路由收益来自哪些任务?数据中还剩多少选模空间? |
其中,Best single model 是最重要的现实基线。如果 router 无法稳定超过它,就意味着动态选模暂时还没有比“永远调用一个强模型”更有价值。
Oracle 则是另一个极端。它无法部署,因为它假设我们事先知道每个模型在每道题上的真实得分,但它与最佳单一模型之间的差距(即 headroom)就是路由在该数据集上最多能获得的提升。后续几乎所有 XPerf 实验,都建立在这套评测逻辑上。
从 Embedding Router 到 Activation Probe
第一轮实验采用的是相对简单、容易复现的方法:先用 MiniLM、BGE、MPNet 等现成的 embedding 模型,把每个 prompt 转换成一组概括文本内容的数字(即 embedding),再根据最相似的历史 prompt(k 近邻,kNN)或一个简单的线性模型(Ridge 回归)预测模型表现。
它们是很重要的 baseline,因为如果直接使用现成的 embedding、不做额外训练就已经足够完成路由,那么引入更昂贵的内部 activation 就没有太大必要。
在此基础上,我进一步尝试了 activation probe。Activation probe 是一个小模型,它读取另一个语言模型(我们称之为 proxy 模型)在处理 prompt 时内部计算出的数值,即 activation。背后的假设是:模型内部状态可能不只编码“这道题在说什么”,还包含题目难度、推理结构和其他与最终模型表现相关的信息。
第一次看到明显的 Router 信号
在一个公开的 routing benchmark 上,我保存了每个 prompt 的 activation,并训练了一个所有候选模型共用的小型神经网络,再为每个模型分别输出预测,这就是 shared trunk 设计。
配置在验证集上选出(验证集不参与训练,专门用于选择设置):读取 proxy 模型的第 52 层,对 prompt 最后 32 个 token 的 activation 取平均,并对三次训练的结果取平均。下表结果来自只用于最终评分的测试集。
| 测试集指标 | 结果 |
|---|---|
| Shared-trunk router accuracy | 64.54% |
| Best single model | 58.63% |
| 绝对提升 | +5.91 个百分点 |
这是一个重要的早期结果。至少在相同 benchmark 集合中的未见 prompt 上,activation probe 已经能够超过固定最佳模型,说明内部表征中确实存在可用于模型选择的信号。
但如果只看 64.54% 这个数字,很容易对结果过于乐观。真正的问题出现在更严格的“未见过的 benchmark”测试中。下表中的 BCE(binary cross-entropy)是衡量概率预测误差的指标,越低越好。
| 未见过的 benchmark 测试 | 结果 |
|---|---|
| 每次留出一个 benchmark 时的 router 准确率 | 56.34% |
| 同一设置下强固定模型 | 58.44% |
| 获得的可用提升比例 | −24.17%(比固定模型更差) |
| 验证集 BCE 最低点 | 约第 3 epoch |
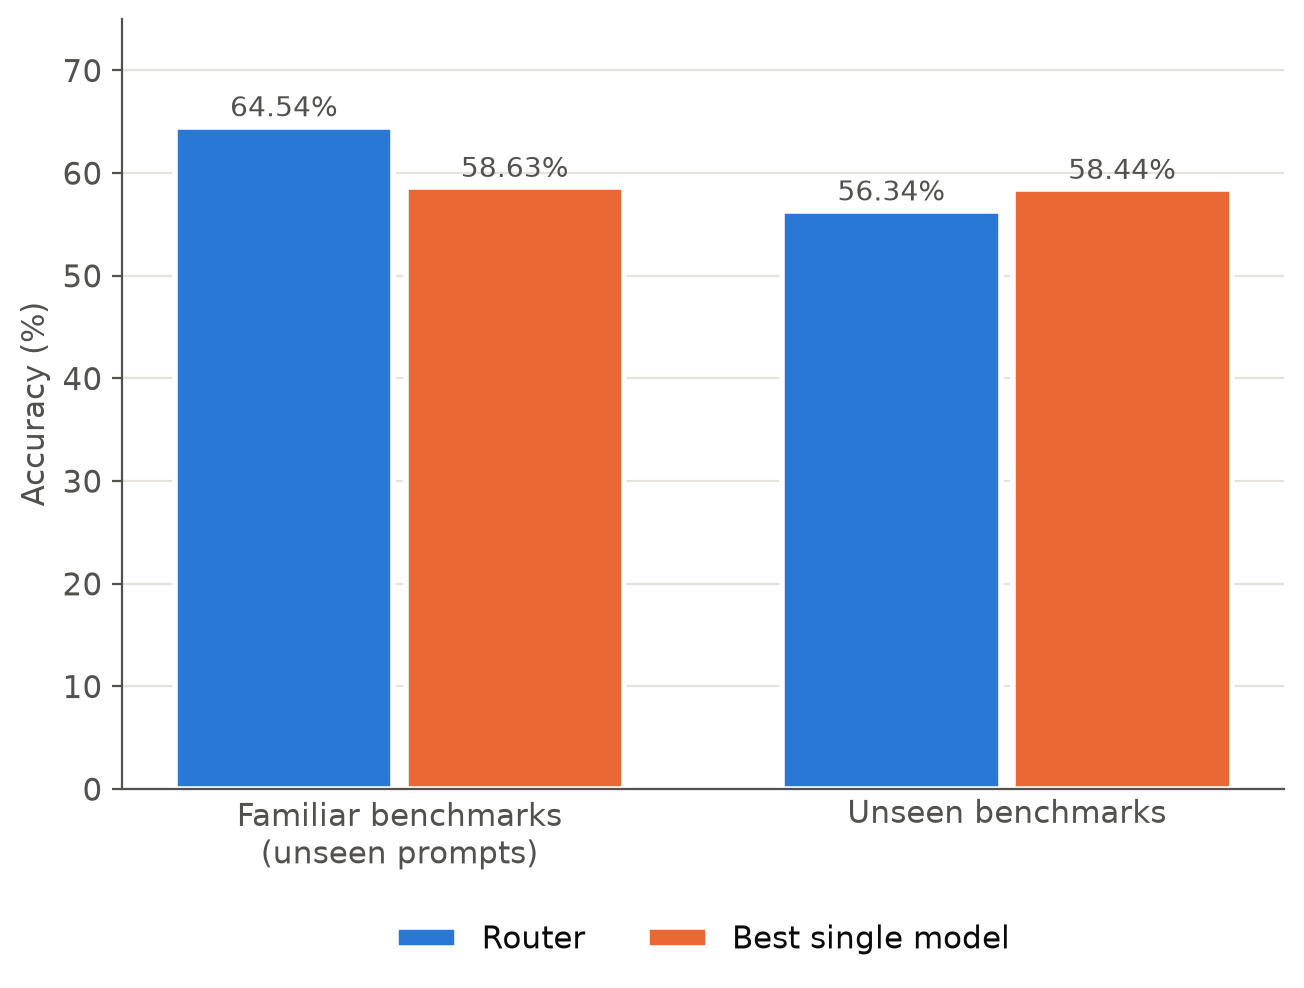
训练过程中,训练误差持续下降,但验证误差大约在第三个 epoch(即完整遍历一次训练数据)后开始反弹。与此同时,一旦把整个 benchmark 留到测试阶段,router 的表现便跌到固定模型以下。
这说明模型在熟悉的任务分布中确实学到了有用规律,但其中相当一部分规律可能与 benchmark 本身绑定得太紧。
换句话说,模型可能已经很会判断:
“这种 benchmark 通常哪个模型比较强。”
但距离真正理解:
“这一个具体 prompt 为什么更适合某个模型。”
还有明显差距。
数据比想象中更重要
这一结果让研究重点逐渐从“继续调模型结构”转向了数据本身。
Routing dataset 有一个很容易被忽视的问题:记录数很多,并不意味着问题足够多样。 十万次模型回答可能只是几千个 prompt 的重复采样,而一个 router 真正需要学习的是不同任务、不同能力和不同模型之间的关系。
因此,在继续训练之前,我先对另外两个数据源做了系统审计:第二个 routing dataset,以及一个大型 benchmark 结果数据库。
第二个 Routing Dataset:先确认这里有没有值得路由的空间
该数据集共包含 43,288 条记录和 14 个候选模型。完成数据检查,并重新划分数据、确保同一个 prompt 不会同时出现在训练集和测试集之后,测试集上出现了一个非常重要的结果:
| 项目 | 结果 |
|---|---|
| 总记录数 | 43,288 |
| 候选模型数 | 14 |
| 官方 split 跨集合重复 prompt | 108 |
| Best single model:o3-mini | 80.91% |
| Oracle | 95.00% |
| 可路由 headroom | 14.10 个百分点 |
Oracle 比最佳固定模型高出 14.10 个百分点,说明这个数据集里确实存在明显的模型选择空间。与此同时,官方划分中有 108 个 prompt 同时出现在训练集和测试集中,这也是重新划分数据的原因。
目前该数据集已经完成审计与训练准备,但尚未提取 activation,也尚未训练新的 probe。
Benchmark 数据库:64 万次回答,其实只有 3,340 个问题
这个 benchmark 数据库的规模看起来更大:
| 审计维度 | 结果 |
|---|---|
| Attempts | 642,752 |
| 独立 prompt | 3,340 |
| 测试运行次数 | 1,067 |
| 不同的模型名称 | 277 |
| Prompt-模型组合(合并重复尝试) | 189,506 |
| Ungraded attempts | 361 |
| 仅有一次评分的 prompt-模型组合 | 66.42% |
这里最值得注意的是第一行和第二行之间的差异。642,752 次 attempts 实际只对应 3,340 个独立 prompt,因此不能简单把几十万条回答当成几十万种不同的训练问题。
重复 attempts 仍然很有价值,它们可以帮助估计同一个模型在同一个问题上的表现分布和不确定性;但它们不能替代 benchmark 和任务类型上的真正多样性。
审计中还确认了几个数据处理细节:N grade 代表不得分,而不是缺失值;361 条未评分的尝试需要排除;66.42% 的 prompt-模型组合只有一次评分;此外,在一个代码 benchmark 中,两个编程 agent 的结果被标错了。两个数据源之间没有发现完全相同的 prompt。
这部分工作虽然没有直接产生新的 router accuracy,却为后续训练建立了更可靠的数据基础。
升级 Routing Dataset:从预测表现到跨模型 Calibration
新的 routing dataset 到位后,我在 GPU 上为它提取了 activation,并首先只用 10 个候选模型都有结果的 prompt 进行训练。
| 数据项目 | 结果 |
|---|---|
| 原始 prompt-模型记录 | 45,409 |
| 独立 prompt | 6,027 |
| 10 个模型都有结果的 prompt | 3,904 |
| 保存的 proxy 模型层数 | 23 |
只使用 3,904 个完整覆盖的 prompt,是为了确保所有候选模型拥有相同的训练机会,避免缺失标签本身影响模型比较。训练、选层与最终测试也严格分离:训练集用于拟合,验证集用于选择层,测试集只在最后报告。
最终在验证集上选择了第 44 层。下表中的 AP(average precision,平均精度)衡量预测能否把某个模型的成功排在失败之前,1.0 为完美。
| 测试集指标 | 结果 |
|---|---|
| XPerf router | 86.22% |
| Best fixed model:GPT-6 Astra | 86.87% |
| Oracle | 90.64% |
| 平均 per-model AP | ≈ 0.949 |
| 仅凭基础比例得到的 AP | ≈ 0.822 |
这一轮实验出现了一个非常关键的矛盾。
平均 per-model AP 已经达到约 0.949,远高于仅凭基础比例得到的 0.822。这说明 probe 对“某个模型会不会成功”拥有很强的预测能力。
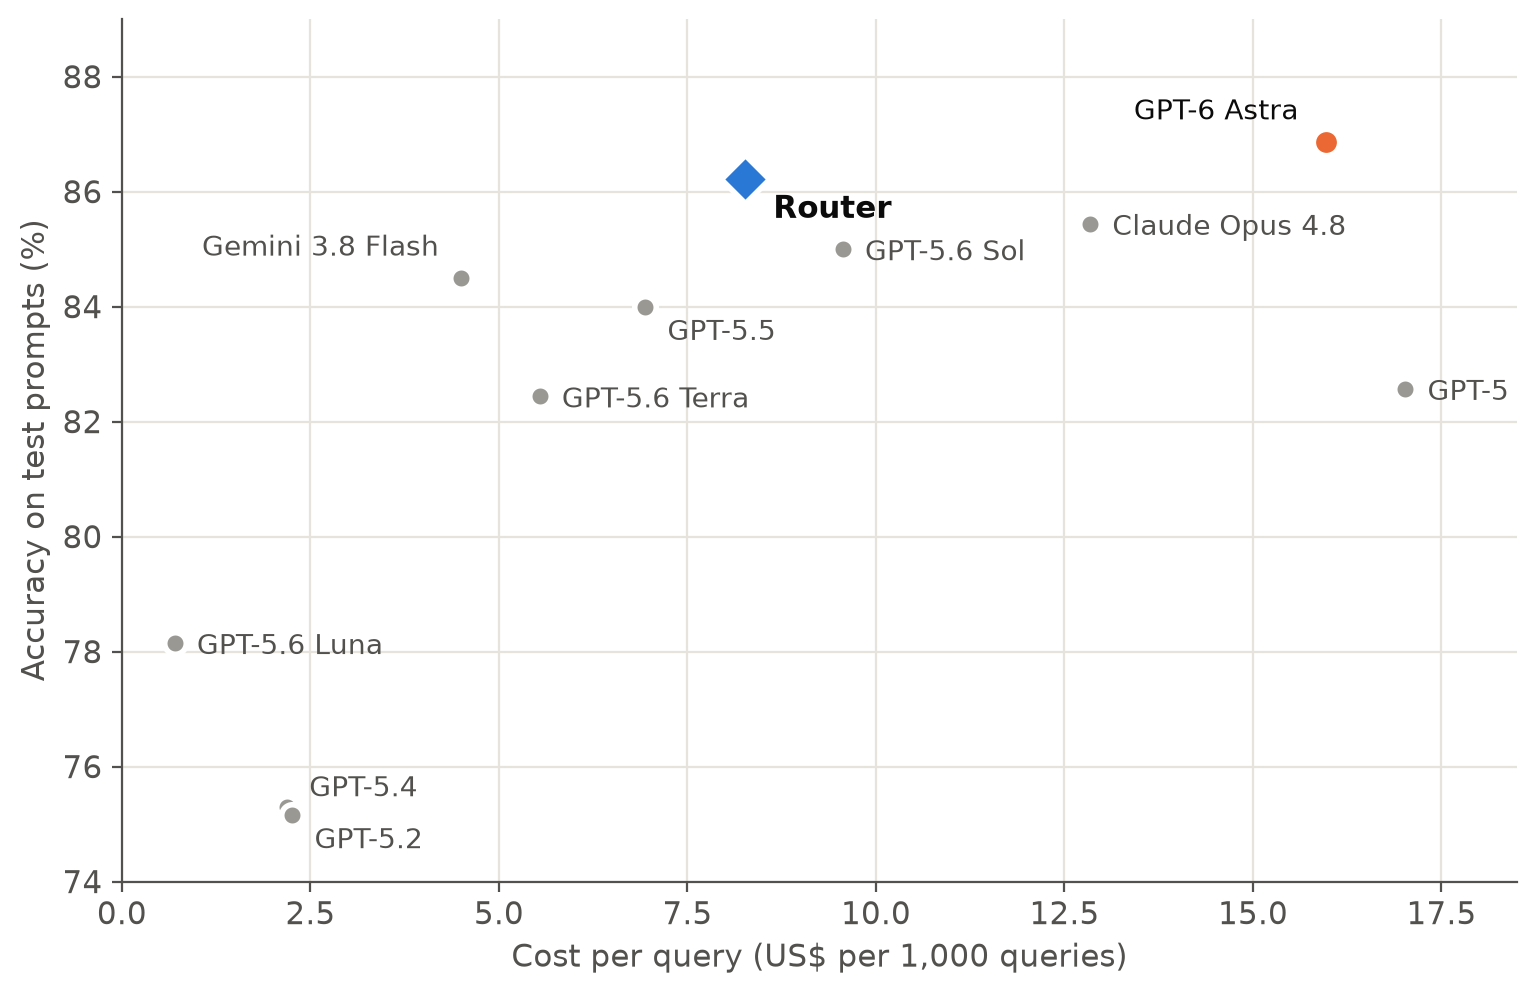
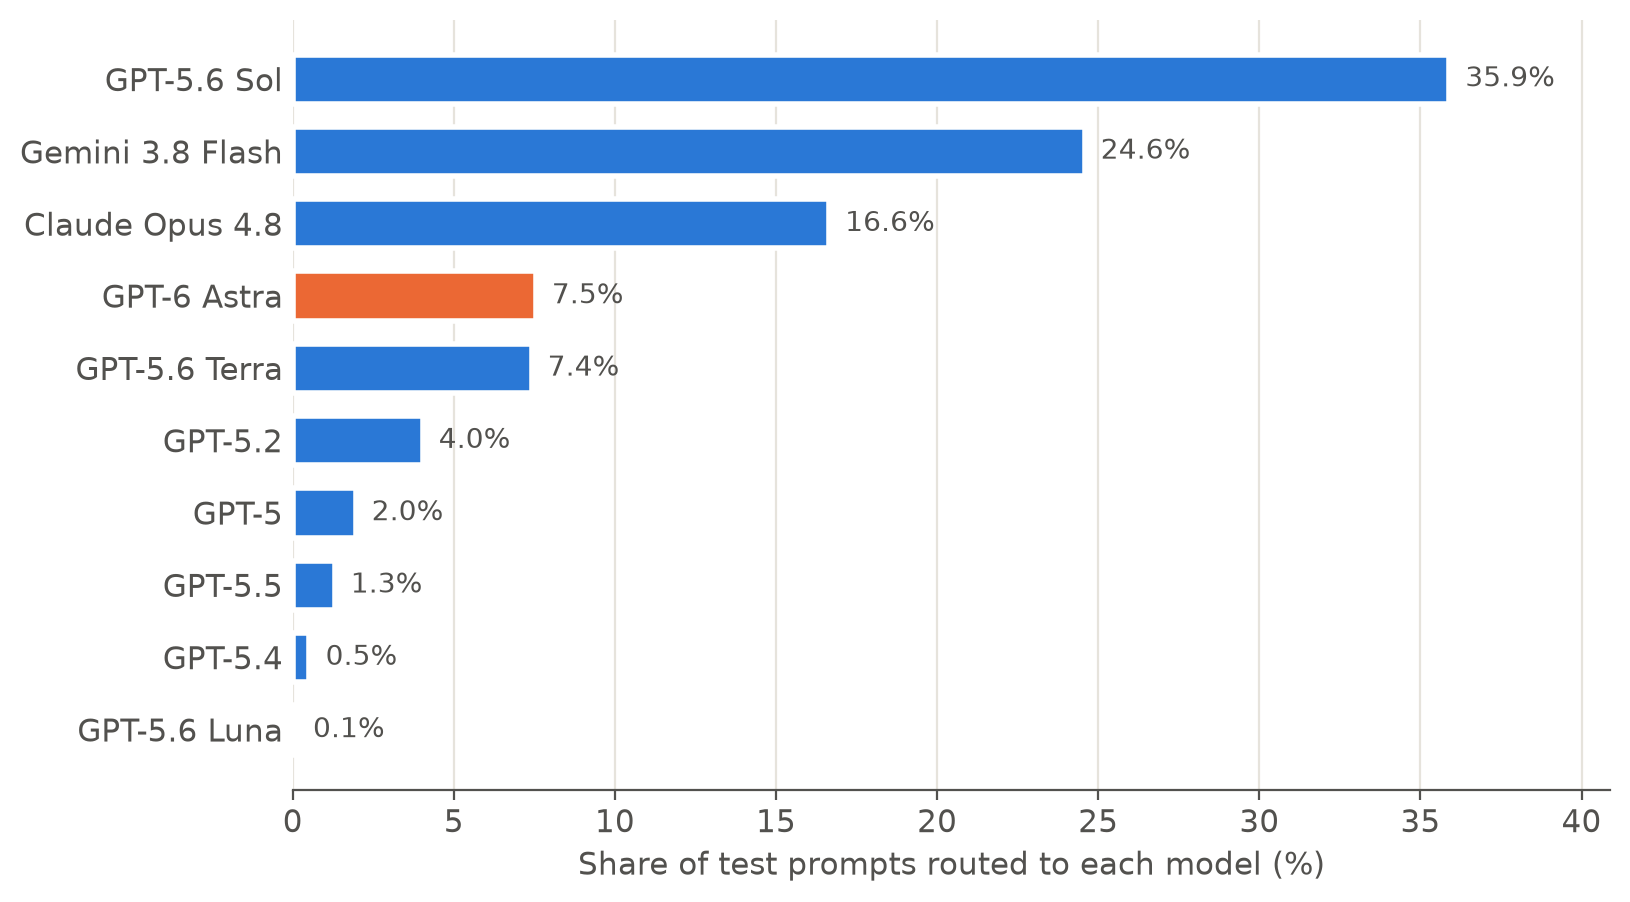
但最终 router 的准确率只有 86.22%,仍略低于固定使用 GPT-6 Astra 的 86.87%。这与最强模型相差不到 1 个百分点,而每次请求的成本约为其一半,因为 router 只把 7.5% 的 prompt 交给了 Astra:
| 准确率 | 每次请求成本 | |
|---|---|---|
| 始终调用 GPT-6 Astra | 86.87% | $0.0160 |
| XPerf router | 86.22% | $0.0083 |
能够分别预测每个模型的表现,并不意味着这些预测已经能够被直接横向比较。
这也第一次把 XPerf 的核心问题明确地指向 cross-model calibration,即某个模型的预测值 0.8 与另一个模型的 0.8 是否代表同样的含义。不同模型的预测概率可能各自很准确,但它们的尺度未必完全一致,因此简单取最大值并不一定会选出最合适的模型。
Shared Trunk:不同模型之间确实存在共享结构
随后,我在数据集的一个中间版本上,比较了“每个模型单独一个网络”和 shared trunk 设计。
| 方法 | 测试集准确率 |
|---|---|
| 每个模型单独一个网络 | 89.71% |
| Shared trunk | 91.43% |
| Best fixed:Gemini 3.8 Flash | 92.57% |
| Oracle | 94.86% |
Shared trunk 比单独网络提高了 1.71 个百分点,说明不同候选模型的表现预测之间存在可以共享的结构,而不是 17 个完全互不相关的问题。
不过,91.43% 仍没有超过 92.57% 的最佳固定模型。也就是说,共享表征让 prediction 变得更好,但“更好的 prediction”依然没有完全转化成“更好的 routing”。
这一阶段也让工作更接近部署:我把 router 连同其设置和诊断结果一起打包,使产品侧能够加载、复现和检查它。
把“表现”和“成本”拆开:XPerf、XLength 与 XCost
随着研究继续推进,系统边界也变得更加清晰。XPerf 最适合专注于预测模型表现,而成本和输出长度应该作为独立信号处理,而不是全部塞进一个 router 中。
因此,后续增加了 XCost 与 XLength。XLength 预测模型对当前请求的回复会有多长(以 token 计),为外层成本估计提供输入;XCost 则用于比较不同路由策略与简单 prompt-length heuristic 的质量—成本关系。
整个架构可以简单表示为:
XPerf   → 预期回答质量
XLength → 预期输出长度

        ↓

外层策略 → 综合质量、成本、延迟与缓存做最终选择
这种拆分的好处是职责清晰。XPerf 不需要自己预测最终账单,XLength 也不需要判断答案质量;产品层可以根据不同使用场景决定如何权衡这些信号。
Activation 的优势,只是因为它“看得更长”吗?
早期 embedding baseline 有一个很明显的潜在不公平因素:MPNet 的输入长度大约只有 384 tokens,而 activation probe 可以看到更长的 prompt。
因此,activation 表现更好可能有两种解释:一种是 activation 本身真的包含更多与模型表现有关的信息;另一种只是 activation 看到了更多文本。
最后这组对比专门用来区分这两个解释。
这组对比使用了一个更大的数据集,包含 11 个 benchmark 中的 7,313 个 prompt 和 17 个候选模型,并有固定的训练、验证和测试集。Embedding baseline 换成了 Qwen3-Embedding-8B,它一次可以读取约 32,000 个 token,因此能够在不截断的情况下编码全部 7,313 个 prompt。其余训练设置保持一致。
最终对比如下:
| 测试误差(BCE,越低越好) | Activation | Qwen3-Embedding-8B |
|---|---|---|
| 所有 prompt 的整体误差 | 0.2497 | 0.3278 |
| 按 benchmark 平均的误差 | 0.2973 | 0.3295 |
Activation probe 在 11 个 benchmark 中的 10 个上取得更低 BCE。
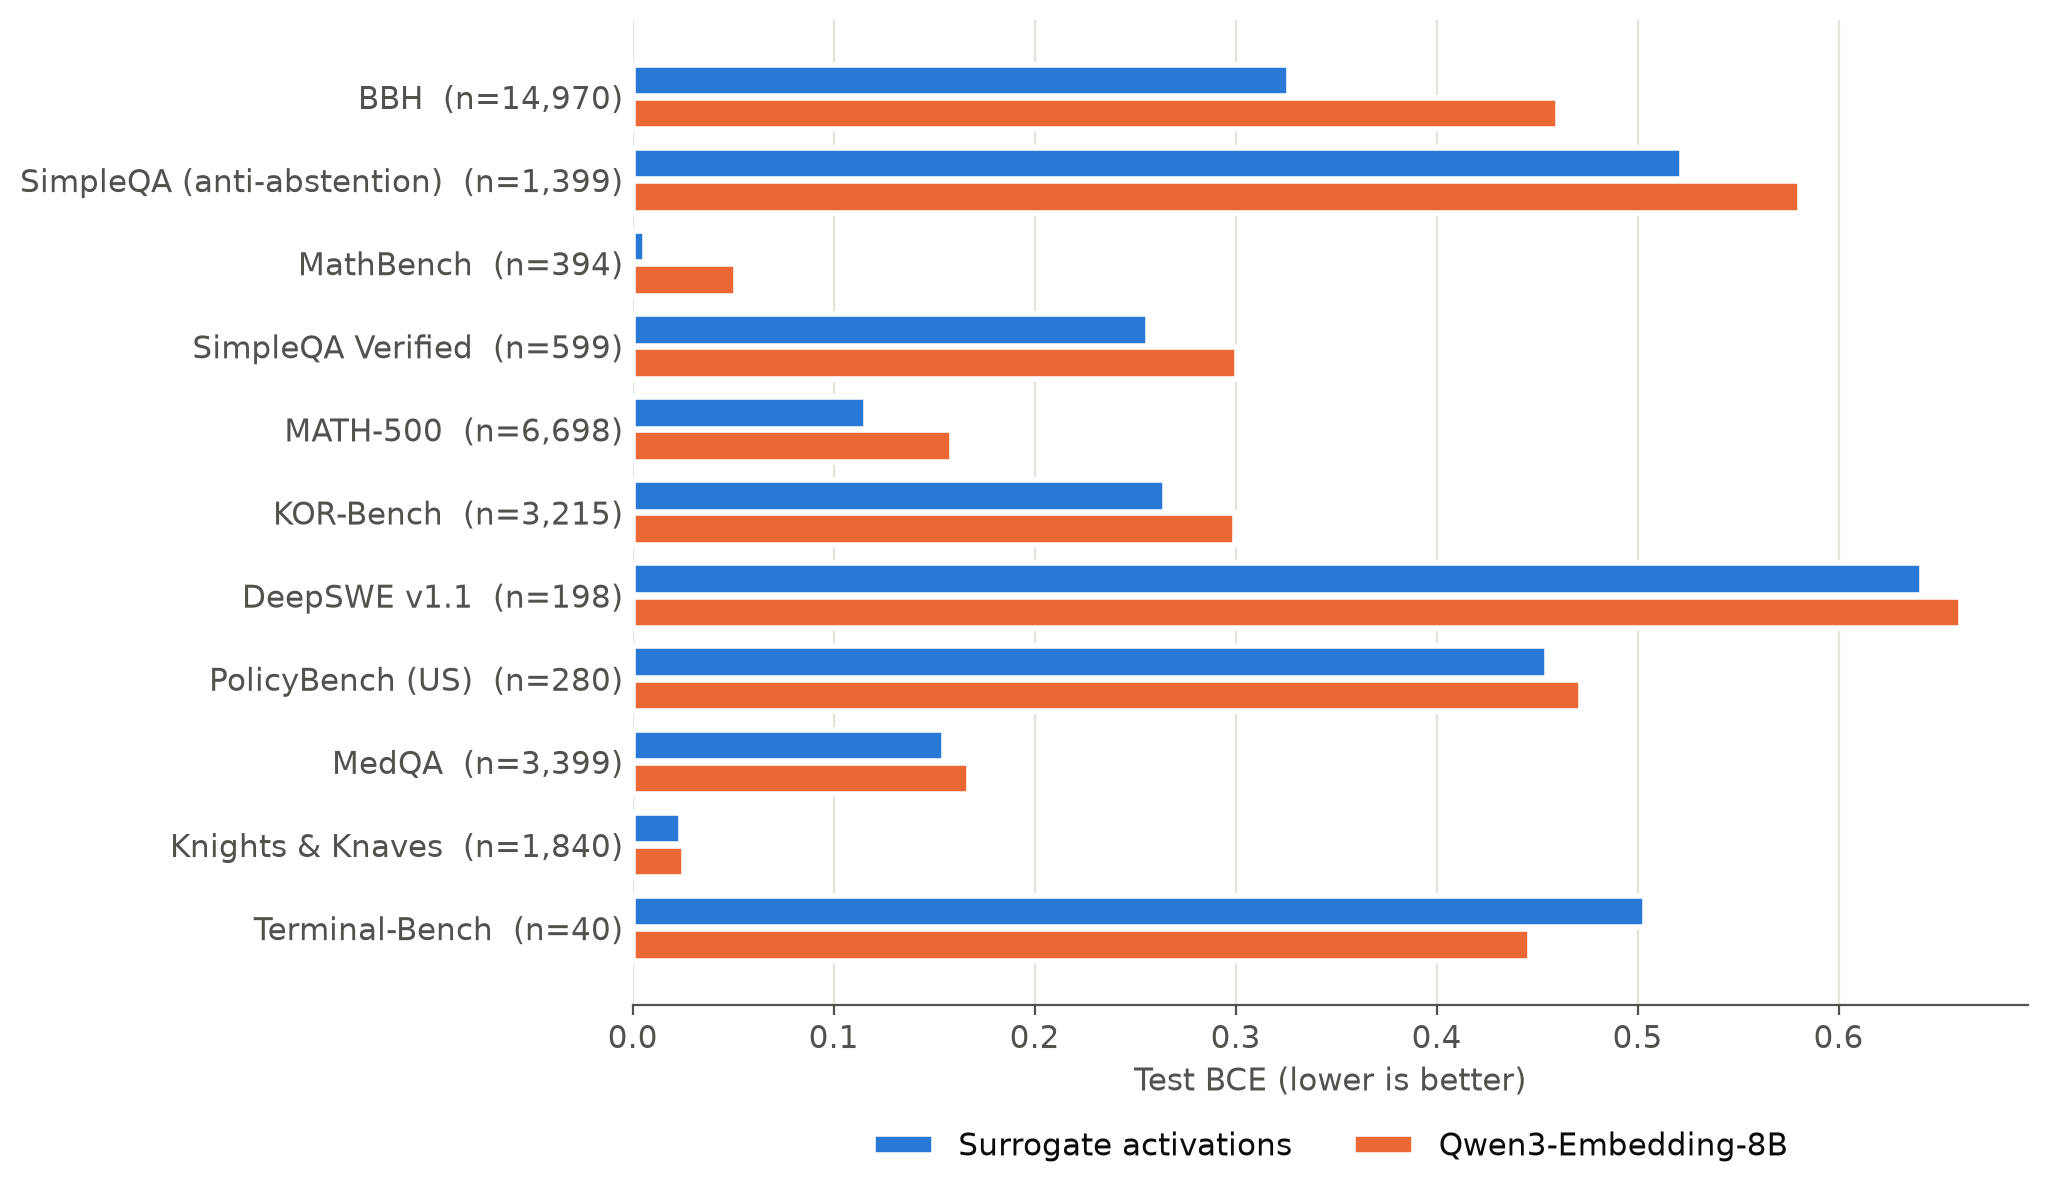
这说明此前看到的优势并不能简单归因于 context window。即便 embedding model 能完整看到长 prompt,proxy 模型(Qwen3.8-27B)第 50 层的 activation 仍然提供了更强的模型表现预测信号。
从目前的实验看,普通 embedding 很擅长描述“prompt 是什么”,而语言模型内部 activation 似乎还能保留一些与“模型面对这个 prompt 会表现怎样”有关的额外结构。
Prediction 已经很强,Router 到底还缺什么?
走到这里,XPerf 已经可以相当不错地预测不同模型的表现,但研究中开始出现一个越来越明显的可能性:模型主要学到了两类信号。
第一类是 Prompt Difficulty——这道题整体有多难;第二类是 Global Model Quality——某个模型平均而言有多强。
这两种信息足以产生非常好的 per-model prediction。例如,当一个非常困难的问题出现时,所有模型的成功概率可能同时降低;简单问题则可能让所有模型的预测一起升高。
问题在于,router 真正需要的不只是这些共同变化。
它还需要知道:
在这一个具体 prompt 上,哪个模型会相对于自己的平均水平表现得更好?
这就是 prompt-specific residual。
一个模型可能整体比另一个模型强,但在代码、数学、事实检索或特定推理结构上,相对优势可能发生变化。真正值得路由的部分,恰恰来自这种 prompt-specific 的相对差异。
下一步:把“预测得准”变成“选得对”
接下来的实验会直接检验上面的假设。
首先是 Residual Target。与其让模型直接预测每个候选模型的原始成功率,可以改为预测它相对于当前 prompt 平均表现的偏差。这样做的目的,是先削弱所有模型共同拥有的 difficulty signal,让模型把更多容量用于学习候选模型之间真正不同的部分。
另一个重要实验是建立一个非常简单、可解释的 Additive Baseline:
它是需要首先排除的最简单解释:也许根本不需要学习复杂的“模型—问题匹配关系”,只要知道题目有多难,再知道每个模型平均有多强,就已经可以解释大部分预测结果。
如果复杂的 activation probe 与这个简单 baseline 表现接近,就说明当前模型主要学习到的仍然是共享 difficulty 和 global model quality。只有当 residual model 能稳定超过这个 baseline,才更有证据说明模型开始捕捉真正的 prompt-specific routing signal。
后续还会测试直接针对路由选择打分的训练目标,例如让模型两两比较排序,以及最小化 regret(相对于最佳选择所损失的准确率),并通过“未见过的 benchmark”测试观察这些信号在新任务上的迁移能力。这里的目标不再只是继续把 BCE 降低一点,而是让训练目标更直接地服务于最终路由决策。
为什么数据多样性可能比模型结构更重要?
目前几个阶段的实验共同指向了同一个问题:router 的瓶颈很可能不只是模型结构,而是训练数据本身。
如果训练数据只覆盖少数 benchmark,一个很强的 probe 完全可能学会识别 benchmark,然后记住“这个 benchmark 通常哪个模型表现最好”。这种策略在新 prompt 来自熟悉 benchmark 时可以获得不错结果,却很容易在“未见过的 benchmark”测试中失效。
因此,下一阶段的数据扩展不会单纯追求更多 attempts,而会更关注 benchmark 和任务类型的多样性、frontier model coverage、记录每条结果的来源、重复测量以及能够支持“未见过的 benchmark”测试的数据结构。所有这些数据源也会逐步标准化到统一的 prompt / model / score 格式,同时保留来源和置信度等信息。
这也是为什么前面的数据审计并不是项目中的辅助工作,而是 router 能否真正泛化的核心部分。
从 Research Probe 到真正可用的 Router
回顾整个项目,XPerf 最初的问题其实很简单:
我们能不能根据一个 prompt 预测不同模型的表现?
目前的实验已经说明,这件事是可以做到的,而且 activation probe 能够提供相当强的预测信号。与此同时,我们也逐步建立起了 embedding baseline、activation 提取、shared trunk 训练、更严格的评测方式、数据审计、XLength 以及可部署的 router。
但真正接近产品的问题比最初的 prediction task 更难:
如何把对模型表现的预测,转化成稳定、可泛化、真正优于固定模型的选模能力?
这意味着下一阶段的重点不会只是继续优化一个单独的 loss,也不会只是让 per-model AP 再高一点。更重要的是确认 XPerf 是否真正捕捉到了不同模型面对同一个 prompt 时的相对优势,并且这种优势能否迁移到训练时没有见过的新任务上。
最终,XPerf 想回答的不是“哪个模型总体最强”。而是:
面对这一次具体请求,哪个模型最适合回答它?
Research period: September 2026
TL;DR: By estimating model performance intelligently, our routing policy came within a point of always calling the strongest model (86.22% vs 86.87% for GPT-6 Astra), at about half the cost per query. Its performance can be improved further by learning how and why model performance differs on a particular type of prompt.
Introduction
Large language models (LLMs) differ in price, speed and ability. A leaderboard is a good starting point, giving an average ranking across various benchmarks. A watertight smart routing scheme needs more, though. A model that is lower on the leaderboard can still be unusually good at factual recall or at a particular style of coding problem. I need some function to predict how well a given LLM will perform on any given prompt. At Telluvian, this is called a model’s ‘expected performance’.
| Candidate model | Expected performance |
|---|---|
| Model A | 80% |
| Model B | 60% |
| Model C | 47% |
Expected performance is only one term in the equation, though. The router also weighs a model’s cost, latency and other product preferences. Expected performance is the answer to a narrower question: how likely is each candidate model to do well on this prompt?
I first used established baselines along with text embeddings. However, the internal activations of a surrogate LLM turned out to be the most effective solution. A lot of work was required to create a suitable training dataset. Predicting model performance wasn’t the toughest challenge, though. The hardest part was untangling a good prediction from a good outcome, which unfortunately were not always aligned.
Expected performance implementation
My router reads the internal activations of a surrogate LLM as it reads the input prompt. A probe on the surrogate then predicts each candidate model’s chance of success. The probe shares one network across all candidate models, with a separate output for each. This worked slightly better than training a separate network per model. Expected cost is calculated separately and is a function of expected reply length and price per token, both of which depend on the model.
Establishing a baseline
Throughout this post, a router's accuracy refers to the share of test prompts on which the model the router selected gave a correct answer. A high accuracy score is not a guarantee of a good scheme, however. For example, a router that sends everything to the most expensive model will score well on accuracy but is clearly lacking overall.
So before training anything complicated, I set up the baselines that every later experiment is measured against.
| Evaluation | What it shows |
|---|---|
| Best single model | How well does always selecting the same model do? |
| Oracle | How well could a router do if it knew the true result in advance? |
| Unseen prompts | Does the router generalise to new prompts from familiar tasks? |
| Unseen benchmarks | Does it transfer to task types that were absent from training? |
| Per-benchmark / headroom analysis | Where does the routing gain come from, and how much room for improvement remains? |
The best single model is the comparison that matters most in practice. Until a router beats it consistently, there's no case for routing over calling one strong model every time.
The oracle is an extreme case. It assumes perfect knowledge, so it always picks a model it knows will answer correctly. Obviously, this can’t be deployed in practice, but the gap between the oracle and the best single model shows how much value routing could potentially add. This is what headroom analysis shows.
“Unseen prompts” and “unseen benchmarks” check whether a router generalises. In the unseen-prompts test, no prompt appears in both the training and test data. In the unseen-benchmarks test, a whole benchmark is held out from training.
Headline result
Over my test routing dataset using 10 candidate models, my routing policy came within a point of always calling the strongest model (GPT-6 Astra) at about half the cost.
| Accuracy | Cost per query | |
|---|---|---|
| Always GPT-6 Astra | 86.87% | $0.0160 |
| Router | 86.22% | $0.0083 |
| Oracle | 90.64% | n/a |
As expected, the oracle sits above both the strongest model and the router. The router called the strongest model 7.5% of the time.
Why doesn’t it beat Astra?
Per model, the router’s predictions are good. The router agreed with the oracle on 95% of model rankings across all prompts. It’s possible there is a calibration error. A predicted 0.8 performance for one model may not actually be equal to a 0.8 for another.
More likely though, it appears that the probe is overfitting on a couple of signals:
- how hard a given prompt is; and
- how good each model is on average.
This can be seen in how the router beat the best single model on seen benchmarks but suffered on unseen ones. For fully effective routing, I need to know accurately which model will beat its own average on a given prompt. I call this the prompt-specific residual.
Next step: turning predictive performance into routing advantage
My next experiments test this directly.
The first is a residual target. Rather than predicting each model's raw chance of success, the probe predicts how far each model sits from the average on that prompt. This strips out the difficulty signal that all models share and makes the probe concentrate on where they differ.
The second is a deliberately simple additive baseline:
It is the simplest explanation to rule out first. Perhaps there's no need to learn how prompts and models interact, and knowing how hard the prompt is and how good each model is already accounts for most of the prediction.
If the activation probe does no better than this baseline, most of its signal comes from shared difficulty and model quality. If a residual model beats it consistently, that is stronger evidence that the probe is picking up genuine prompt-specific signal.
I also plan to try training objectives that score the routing choice directly, such as ranking models against each other in pairs and minimising regret (the accuracy lost compared with the best possible choice), each measured on the unseen-benchmarks test. At this point, a training objective closer to the routing decision is worth more than a slightly lower BCE.
Data diversity and cross-task generalisation
A number of the results point in the same direction. The bottleneck appears to be the variety and volume of training data rather than the routing policy itself. If the training data covers only a handful of benchmarks, a probe can learn to recognise each benchmark and will overfit on them. You can see this in the router’s weaker performance on unseen benchmarks. A clear next step is therefore to increase data diversity and work on cross-task generalisation.
From research probe to deployable router
This research started with a simple question: can I predict how different models will perform from the prompt alone? Happily, the answer seems to be yes!
Half the cost for almost the same quality is a good start. The real prize is a router that beats the best model outright, by knowing which model wins on each prompt rather than on average. That’s what I’m working on deploying.
